AudioVText
Deployment
Overview
About AudioVText
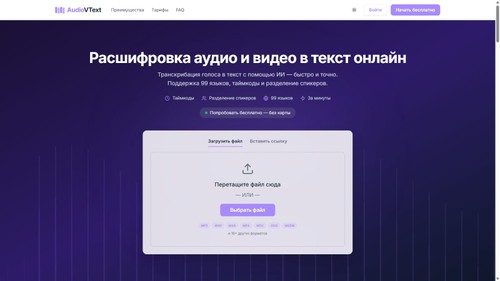
AudioVText converts audio and video into text using AI speech recognition. The service is built for long recordings: interviews, meetings, lectures, podcasts and calls. AudioVText supports 99 languages. Russian is its primary language and the service is tuned specifically for it. Every transcript receives automatic timecodes, so any phrase can be traced back to the moment it was said. AudioVText separates speakers, so a multi-person conversation reads as a dialogue instead of one block of text.
The service also generates a short summary of each recording. Files can be uploaded directly, or imported by pasting a link to a video on YouTube, VK Video, Rutube or OK.ru. Finished transcripts export to TXT, SRT, VTT, DOCX and PDF, which fits both subtitle and document workflows. AudioVText runs in the browser and requires no installation. Uploaded files stay confidential: they are stored encrypted, are never used to train models, and are deleted automatically.
At a glance
Software information
Industries served, licensing and the support AudioVText provides.
Industries
- Media-production
- Education-management
Licensing
- Proprietary
- Monthly Payment
- Annual Subscription
- Free version
Support
- Support daysMondayTuesdayWednesdayThursdayFridaySupport time09:00 to 18:00 (EET)
Knowledge Base
Capabilities
AudioVText features
The full feature set, grouped by module.
Plans
AudioVText pricing
Media
Screenshots & video